Important note: On September 7, 2026, the KITTI and KITTI-360 servers had to be restored to the backed-up state of August 7, 2026. Results within this period have to be resubmitted.

Method

MonoHMP: Monocular 3D Object Detection with Hybrid Visual Encoding and Multi-scale Depth Prediction [MonoHMP]
[Anonymous Submission]

Submitted on 3 Nov. 2026 02:09 by
[Anonymous Submission]

Running time:0.048
Environment:1 core @ 2.5 Ghz (C/C++)

Method Description:
MonoHMP is a monocular 3D object detection
framework that predicts 3D bounding boxes from a
single RGB image. It combines a hybrid visual
encoder with a multi-scale depth predictor to
extract visual and depth features. Geometry-aware
dynamic anchor queries guide the decoder, and
mixed supervision is used during training. The
method is evaluated on the KITTI 3D object
detection benchmark.
Parameters:
Backbone: ResNet-50; input resolution: 1280 x 384;
depth bins: 80; inference batch size: 1.
Latex Bibtex:

Detailed Results

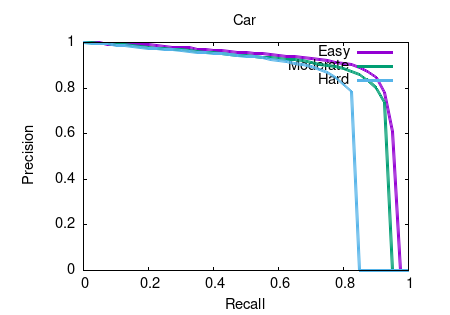
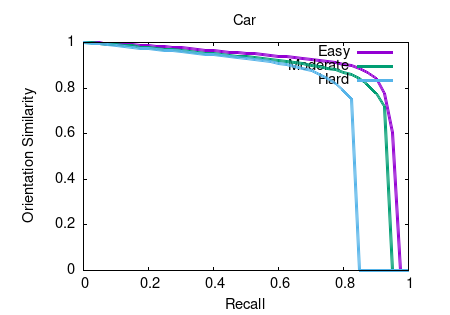
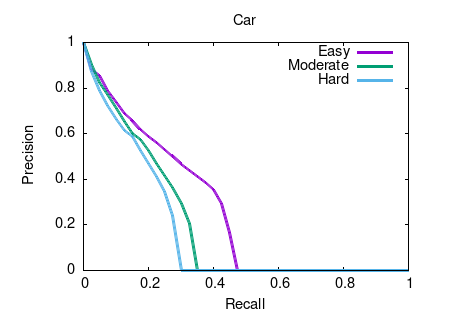
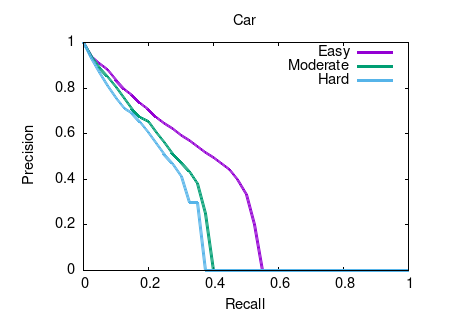
Object detection and orientation estimation results. Results for object detection are given in terms of average precision (AP) and results for joint object detection and orientation estimation are provided in terms of average orientation similarity (AOS).


Benchmark Easy Moderate Hard
Car (Detection) 89.24 % 86.34 % 77.27 %
Car (Orientation) 88.99 % 85.65 % 76.46 %
Car (3D Detection) 24.81 % 18.30 % 15.62 %
Car (Bird's Eye View) 32.65 % 23.72 % 21.40 %
This table as LaTeX


2D object detection results.
This figure as: png eps pdf txt gnuplot


Orientation estimation results.
This figure as: png eps pdf txt gnuplot


3D object detection results.
This figure as: png eps pdf txt gnuplot


Bird's eye view results.
This figure as: png eps pdf txt gnuplot


eXTReMe Tracker